01·LLMyüksek olan daha iyi
Dil modeli
90,54%
Gemma 3 27B modelinin +4,47 önünde
- 01Airun LLM90,54
- 02Gemma 3 27B86,07
- 03DeepSeek-R1 32B74,99
- 04Qwen3 30B69,56
Yanıt doğruluğu, %. Görevler Kırgızca.
Beş ölçüm, beş birincilik.
KarşılaştırılanlarGemma 3 27BDeepSeek-R1 32BQwen3 30BKani TTSAitil.kgClaude Opus 4.6Aitil.kg TranslateGPT-5.4Grok 4.20
90,54%
Gemma 3 27B modelinin +4,47 önünde
Yanıt doğruluğu, %. Görevler Kırgızca.
6,39%
En yakın rakipten 3,2 kat daha az hata
WER — 100 kelimedeki hata sayısı. Yalnızca Kiril.
52,9
Claude Opus 4.6 modelinin +6,9 önünde
BLEU — referans çeviriye yakınlık.
Yapay zekânın Kırgızcayı ve Orta Asya'nın diğer dillerini nasıl anladığını araştırıyoruz.
Yayın yerleriMeLLMMRLLoResMTClimateNLParXiv
MeLLM 2026·ACL Anthology2026.mellm-1.5
Zarina Uvalieva, Bektemir Kumarbai Uulu, Adilet Metinov, Tynchtykbek Tashbaltaev, Nurtilek Alibekov
Abstract
Text normalization, the task of converting noisy, informal text into a standardized form - is a fundamental preprocessing step for many NLP applications. Despite the growing need for Kyrgyz language processing tools, to the best of our knowledge, no prior work has addressed automatic text normalization for Kyrgyz, a morphologically rich, low-resource Turkic language. In this paper, we present the first systematic study of Kyrgyz text normalization. We collect a dataset of 1.67 million noisy–clean text pairs sourced from YouTube comments, Instagram posts, and Telegram channels, where users frequently write without punctuation, capitalization, or standard spelling. Pairs were annotated with Gemini 3 Pro; the 1,000-example test set was fully verified by two native Kyrgyz speakers with adjudication, and a random subset of the training data was spot-checked, while the full 1.67M training set was not verified exhaustively. For continual pre-training, we additionally use a 538 MB Kyrgyz corpus compiled from news portals and books. We evaluate five systems: a rule-based baseline, zero-shot mT5, a fine-tuned mT5-small model, a continually pre-trained mT5-small followed by fine-tuning, and zero-shot Gemma 4. Our experiments show that fine-tuned mT5-small achieves a CER of 0.0796, outperforming the rule-based baseline (CER 0.2029), zero-shot mT5 (CER 0.9887), and zero-shot Gemma 4 (CER 0.1620), a roughly 32× larger model in a fine-tuned vs. zero-shot setting. Human evaluation by two native Kyrgyz speakers confirms these results, with fine-tuned mT5-small rated as correct in 99.8% of cases. We further analyze why continual pre-training with span corruption does not improve over direct fine-tuning, finding hallucination in 35/40 of the inspected failure cases (87.5%, 95% Wilson CI [74%, 95%]).
Proceedings of the 1st Workshop on Multilinguality in the Era of Large Language Models (MeLLM 2026), pages 52–62July 2026 ©2026 Association for Computational Linguistics52
Sosyal medyadan 1,67 milyon çift üzerinde ilk sistematik çalışma: sinir ağı kurallardan 2,5 kat daha az hata yapıyor.
Yol, alışveriş, belgeler ve yasalar: şehirde ihtiyacınız olan her şey.
Proyalnızca Airun Pro aboneliğiyle
Tüm ülke Airun'a bağlı
ListedeBankalar 2Devlet 3Eğitim 8İş 9
Bankalar
Bakai Bank
Bankalar
Берекет Банк
Devlet
Жогорку Кенеш
Devlet
Министерство юстиции
Devlet
Мэрия Бишкека
Eğitim
Университет Манас
Eğitim
Университет Ала-Тоо
Eğitim
КГМА
Eğitim
КРСУ
Eğitim
МУК
Eğitim
AUCA
Eğitim
Compass College
Eğitim
Nomad College
İş
mTicket.kg
İş
Etnomedia
İş
1.1 studio
İş
OnClinic
İş
ArtWin
İş
Devolution
İş
Profile.kg
İş
Bakai Store
İş
Bakai Travel
Hakkımızda yazanlar
The Times of Central AsiaSputnik КыргызстанToday.kgEconomist.kgBanks.kgReporter.kgKaktus.mediaTHE TECHАкчабарРамблер/новости
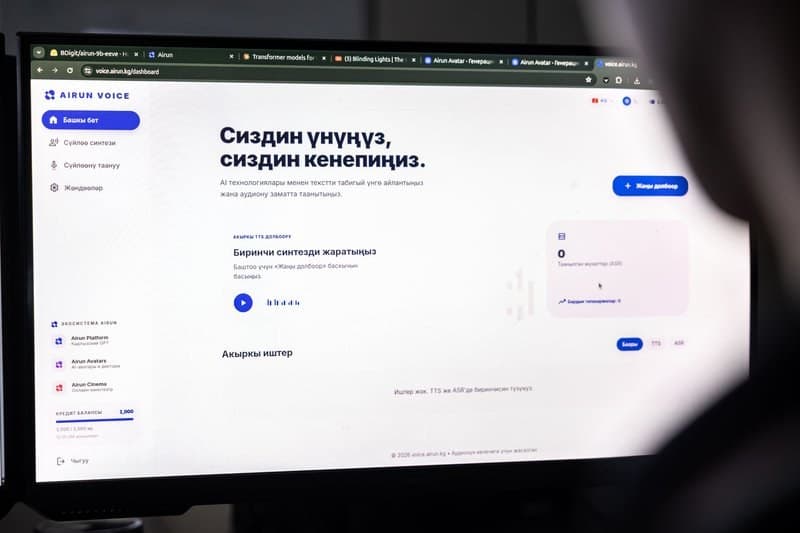
Kendiniz için: tarayıcıda ve telefonda. Ürününüz için: API ile Airun modelleri.